
22. The T-test and the 1918 influenza pandemic#
The CDC (https://archive.cdc.gov/www_cdc_gov/flu/pandemic-resources/1918-commemoration/pandemic-timeline-1918.htm) writes that In 1918, a new influenza virus emerged. During this same time period World War I was taking place. The conditions of World War I (overcrowding and global troop movement) helped the 1918 flu spread. The vulnerability of healthy young adults and the lack of vaccines and treatments created a major public health crisis, causing at least 50 million deaths worldwide, including approximately 675,000 in the United States.
Markel et. al. wrote a paper that collected non-pharmaceutical intervention data and studied it’s realtionship to public health outcomes dduring the 1918 pandemic for 43 US states.
Let’s explore the T-test and use this test to compare public health outcomes between those states that did and did not quickly implement non-pharmaceutical interventions.
The dataset we will use is on course site and called 1918 NPI Pandemic data.
Question 1 Please download the dataset on course site, compute the median number of days until public health response (using the variable public_health_response_time_days) and split your dataset into two: those states with a public health response before the median number of days and those states with a public health response at or greater than the median. Please report the number of states before and after the median as well as the median number of days.
What exactly is the Student T distribution (a multi-part journey)?#
If our goal is to characterize the total number of excess deaths due to influenza and/or pnemonia in the states that implemented an early vs late public health response then we can use the Central Limit Theorem (CLT).
The CLT says that if we collect \(n\) data points \((d_{1},d_{2},\cdots,d_{n})\), and we assume that these data points were generated from \(n\) random variables \((X_{1}, X_{2}, \cdots, X_{n})\), and we assume that every random variable \({X_{i}}_{i=1}^{N}\) all have the same distribution, and we assume that these random variables are independent (sheesh) then \( \frac{\sum_{i=1}^{n} X_{i}}{n} \sim \mathcal{N}(\mu, \frac{\sigma^{2}}{n} )\)
Our goal is to learn about \(\mu\) and we assume that this parameter is unknown. We need to figure out \(\sigma^{2}\) but we have a problem. We don’t know \(\sigma^{2}\). We need to estimate it.
Question 02 Please estimate the variance and standard deviation for the total number of excess deaths due to influenza and pnemonia for both “early” and “late” response states. You can use the following formula \(S = \frac{1}{n-1} \sum_{i=1}^{n} ( d_{i} - \bar{d} )^2 \) where \(\bar{d}\) is the mean of the data points.
From variance to Chi squared (Part 2)#
If we assume that our data \(\mathcal{D} = (x_{1}, x_{2}, \cdots, x_{n})\) are all normally distributed \((x_{i} \sim \mathcal{N}(\mu,\sigma^{2}) )\) then
so then
and
Then we can substitue in
Lets use this information to compute a 95% confidence interval for our estimate of \(\sigma^{2}\) in the early and late public health action states.
Question 04 (A) Please compute the 2.5th and 97.5th percentile values for a \(\chi^{2}_{n-1}\) for the early and late action groups. Note that these numbers wil be different if the sample size for each group is different. You can compute these values in your favorite software or you can google them (ie look them up). (B) We know from the above that \(P\left[ \chi^{2}_{n-1}(2.5) < \frac{(n-1) S}{\sigma^{2}} < \chi^{2}_{n-1}(97.5) \right]\). Please use this equation so that the paramter \(\sigma^{2}\) is along sindie this double-sided inequality. \(P( \text{stuff} < \sigma^{2} < \text{stuff} )\) (C) Please compute a 95% confidence interval for \(\sigma^{2}\) for the early and late actions states.
A montecarlo estimate of the t-distribution (Part 3)#
Well we know that \(\bar{X} \sim \mathcal{N}(\mu,\frac{\sigma^{2}}{n})\). We also know now that when you dont have the true paramter value \(\sigma^{2}\) that we can estimate it with the relationship \(\frac{(n-1)S^{2}}{\sigma^{2}} \sim \chi_{n-1}^{2}\).
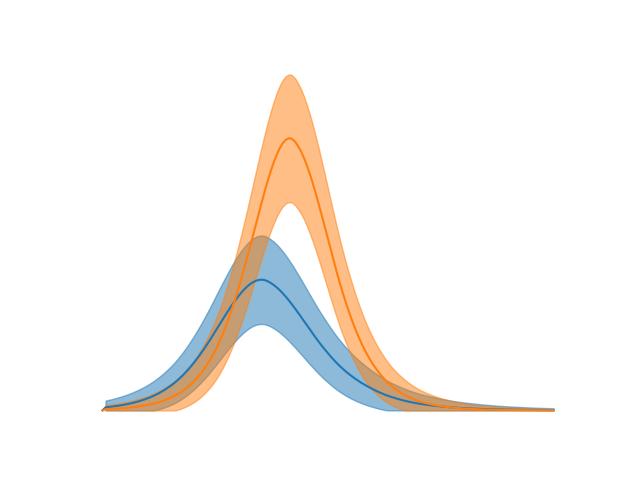
One way to understand the impact of an uncertain estimate of \(\sigma^{2}\) is to simulate a set of potential \(\sigma^{2}\) values, assume each one is fixed in turn, and then generate a \(\bar{X}\) sample as if \(\sigma^{2}\) was known.
Question 05 (A) Please use your favorite statistical software to simulate 1000 \(\sigma^{2}\) values using the relationship \(\frac{(n-1)S^{2}}{\sigma^{2}} \sim \chi_{n-1}^{2}\) for the early states only. Lets call those lists \(V_{\text{early}}\) and \(V_{\text{late}}\). (B) For each sample, \(\sigma^{2}_{i}\) in \(V\), sample a value from \(\mathcal{N}(0,\sigma^{2}_{i}/n)\) and store that a list \(M_{\text{early}}\). (C) Now lets assume that there is no variablity in \(\sigma^{2}\). Please generate a list of 1000 values from the distribution \(\mathcal{N}(0,S^{2}/n)\) (note that its the same \(S\) all 1000 times). Please compare the histograms genertaed from samples in (B) and (C). In other words, what does uncertainty in \(\sigma^{2}\) “do” to the normal distribution?
Ok the t-distribution (Part finally)#
The empirical distribution you generated above has a specific probability density function and is called the Student’s t distribution with mean \(\mu\), variance \(\nu\), and \(n-1\) degrees of freedom. In other words, you need three parameters to specify a t-distribution.
Question 06 Please plot the proability density from -3 to 3 for the following three distributions: \(\mathcal{N}(0,1)\), \(\mathcal{T}(0,1, 3)\), \(\mathcal{T}(0,1,30)\) where \(\mathcal{T}(\mu,\sigma^{2},n)\) is a t distribution with expected value \(\mu\), variance \(\sigma^{2}\), and degrees of freedom \(n\). Having gone through the above exercises, why are \(\mathcal{T}(0,1, 3)\) and \(\mathcal{T}(0,1, 30)\) different? Why are \(\mathcal{N}(0,1)\) and \(\mathcal{T}(0,1, 30)\) different?
A t-test for public health response timing and disease burden for the 1918 flu pandemic#
A two sample t-test provides evidence for (or against) the hypothesis
When we don’t know the variance from our sample (per usual)
Because we are estiating the variances, this statistic has a T distribution with (assuming the null hypothesis is true) expected value 0 or \(\mathcal{T}(0,SE,df)\) . The degrees of freedom are beyond the scope of this homework. Note that they are usually approximated.
Use your favorite software to compute a two sample t-test for excess deaths due to influenza and pneumonia between the early and late intervention states. Please return a description of: the estimate t-statistics (what does it mean?), pvalue (what does it mean)?, and the conclusion you would draw from conducting this test?