Introduction
The foundations of probability are built on sets, yet data is more naturally stored and more easily computed on if it is represented numerically.
Random variables match each outcome in our sample space to a value on the number line.
In addition to computational advantages, random variables help us extract from our data the most important characteristics, and they serve as building blocks which we can use to create powerful models. Random variables are also a language we can use to communicate our modeling efforts to other mathematicians, statisticians, and data scientists.
Suppose we hypothesize that the frequency of social media posts on some popular outlet are related to influenza-like illness (ILI)---a syndromic diagnosis suggesting a patient may have influenza. A patient is diagnosed with ILI if their temperature is measured to be at or above 38C and symptoms resembling the flu. Because influenza is most active in winter and spring, we collect a random sample, each day, of social media posts from September to May and in addition we collect the proportion of patients who are admitted to the hospital and are diagnosed with influenza-like illness at the US national level.
The above hypothesis, data collection, and future inference has numerous details. However, we will see shortly that we can simplify our hypothesis by using random variables.
Maps from the sample space to the number line
Given a sample space , a random variable, (e.g. ), is a function from each element in ---from each outcome---to a value on the real number line. The real number line contains all numbers: integer and decimal, from negative to positive infinity.
Example: Suppose our sample space contains two elements . We may decide to define a random variable that maps the outcome to the value -1 and the outcome to the value 1. In otherwords, and . We could as well define a random variable on the same sample space such that and .
Example: Suppose our sample space contains all integers from 0 to 1000 . We may be most interested in when an integer is even or odd, and so we can define a random variable when , our outcome, is an odd integer and when is even. This is an example of how a random variable can distill down a sample space with many outcomes into a random variable with two.
Example: Suppose we decide to study the relationship between the cumulative total number of cigarettes smoked by a person form the date that they started smoking and the presence of lung cancer. We define our sample space to be . We define two random variables, a random variable that maps the outcome to the value in the first position , and a random variable that maps the to the value in the second position . Though our outcomes are linked, we can use random variables to think about two separate outcomes---cigarettes smoked and lung cancer---and how they interact.
A new sample space
When we build a random variable that maps outcomes to values on the number line we create a new sample space which we will call the support of or . Define a sample space without outcomes . Then the support of X is
Our new sample space is the set of all the potential values that our random variable can produce. This is a sample space linked to , but in practice after we develop a random variable we often no longer reference .
In our above example where , the random variable has support and . Lets look at another example, when above is the set of all integers from 0 to 1000. Even though the sample space is quite large, the random variable that maps the integers to 0 when they are odd and 1 when even has a small support .
How to assign probabilities to a random variable
Random variable themselves do not require that we include the probability of each of their values. Random variables are a function from outcomes to the real numbers---nothing more. That said, in practice we build random variables expecting that the probabilities we assign to outcomes in our sample space will correspond to probabilities assigned to values of our random variable.
We assign a probability to the value , which belongs in the support of random variable , the sum of the probabilities of all the outcomes that maps to .
where each outcome is mapped by to the value . In other words, for each of .
Define a and a random variable that maps the outcomes to the following values
Outcome P(outcome) X(outcome)
  a         0.1           0
  b         0.25          1
  c         0.15          1
  d         0.3           2
  e         0.2           0
We assign the probability that as the sum of the probabilities assigned to outcome and outcome , or
We can run the same procedure for all the elements in the support of ,
and organize our work in a table
X P(X=x)
0 0.30 1 0.40 2 0.30
A probability distribution for a random variable is a set of tuples where the first position in each tuple is a value in the support of and the second position in the tuple is the corresponding probability assigned to that value.
A probability distribution for the random variable above is .
Imagine we run an experiment that collects data on marathon runners. We decide to collect the number of elapsed minutes until they finish the race. Our sample space is defined as all positive integers . We may decide to build a random variable that maps outcomes less than 60 to the value 1, outcomes from 61 to 120 to the value 2, and outcomes greater than 120 to the value 3. One potential probability distribution for is . For this probability distribution, , , and .
A sample space Ω with elements {a, b, c, d, e} and a random variable X that maps each element in Ω to one the values: 0, 1, or 2. Probabilities corresponding to outcomes in the sample space and how they map to probabilities for each value of X are shown in blue.
Probability mass function
There are several supportive tools that we can use to help us better understand random variable we create. The first is the probability mass function, or p.m.f. The probability mass function is a [function]{.underline} that maps values in the support of a random variable to their corresponding probabilities. Inputs are values of , outputs are probabilities.
The probability mass function is a convenient way to organize a probability distribution and it allows us to transfer all the information we know about functions to random variables.
Define a random variable with support , probability distribution {(-1,0.2),(0,0.5),(1,0.3)}, and probability mass function
The function---our probability mass function---is a type of function called a piecewise function.
We can ask our pm.f. to return the probability for a given value
and we can visualize our probability mass function using, for example, a barplot.
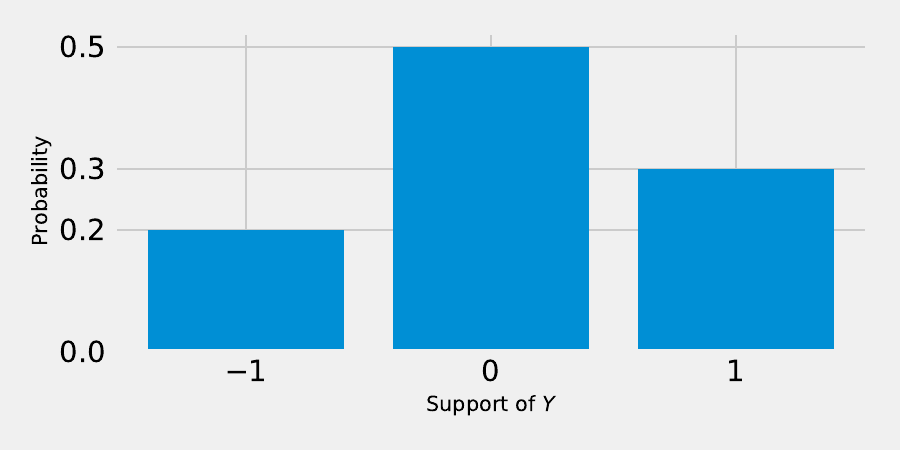 {#fig-pmfviz}
Distributed as : Because we can use the probability mass function to describe the probability distribution of a random variable, we will often write
The above formula is read "the random variable is distributed as ", and what we mean when a random variable is distributed as is that the support of is the same as the domain of the function and that the probability of a value is equal to , or
The probability mass function is a convenient method for assigning probabilities to random variables and visualizing the distribution of a random variable.
Cumulative mass function
The cumulative mass function is a [function]{.underline} that maps values in the support of a random variable to the probability that the random variable is less than or equal to this value, or .
We use a capital to denote a cumulative mass function (c.m.f). The c.m.f. corresponding to random variable has a domain equal to the support of and produces values between 0 and 1 (the values a function can produce is called the function’s image).
The c.m.f. too can be visualized and we could also use the c.m.f. to describe the probability distribution of a random variable. This is because we can use the c.m.f. to derive the p.m.f.
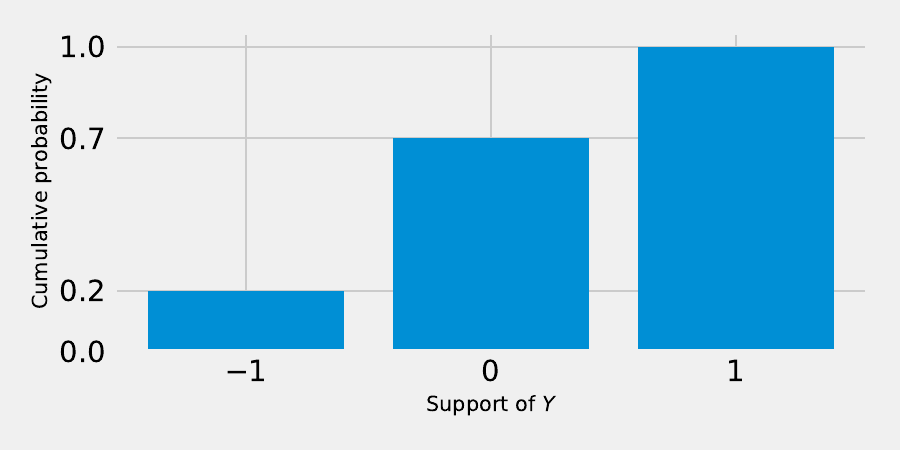 {#fig-pmfviz}
For a random variable
The c.m.f is then
We can use the c.m.f to compute any p.m.f () too by noticing that for a support where the values in this set are ordered form smallest to largest
Because the p.d.f. and c.m.f equivalently describe the probability distribution of a random variable we can write or .
Two or more random variables
A single random variable is a useful way to describe a sample space and the probabilities assigned to values on the number line corresponding to outcomes.
But more complicated scientific questions often require several random variables and rules for how they interact. We will explore how to generate multiple random variables on the same sample space. Then we will develop an approach to define probabilities for combinations of random variables, a joint probability mass function and joint cumulative mass function.
Suppose we design a sample space and build two random variables on this space and . Because and are random variables we can think of the support of and support of as two new sample spaces. Lets assume that the outcomes in and that the outcomes in . Then we can define a new set of outcomes in the space for all combinations of from 1 to and from 1 to .
This new space above maps outcomes in to a tuple where the outcomes were mapped by to the value and by to the value . If we assign the probability of to be the the sum of the probabilities of all outcomes in that maps to and maps to then we call this a joint probability distribution.
A pharmaceutical company launches a clinical trial to study adverse events from a novel medicine. The trial enrolls patients and randomizes them to receive the novel drug or optimal medical therapy. The trial expects three potential adverse events which we call , , and . We may choose to define a sample space and further build a random variable that maps outcomes to values 0 when an adverse event was experienced by a control patient and 1 when an adverse event was experienced by a novel drug patient, and a random variable that maps adverse event 1 to the value 1, adverse event 2 to the value 2, and adverse event 3 to the value 3.
Event X1 1 1 0 0 0
Event Y1 2 3 1 2 3
A joint probability distribution would assign probabilities to all possible pairs of values for and .
X Y prob
1 1 0.1 1 2 0.05 1 3 0.23 0 1 0.05 0 2 0.30 0 3 0.27
We write to denote the probability assigned to the joint probability that the random variable equals the value and the random variable equals the value . With the above example in mind, and this probability could be described as the probability an OMT patient experiences adverse event 2.
Joint probability distributions are often visualized as a table with one random variable’s values representing the rows and the second random variable’s values representing the columns
Y = 1 Y = 2 Y = 3X=0 0.05 0.30 0.27 X=1 0.10 0.05 0.23
A joint distribution can be used to compute probabilities that the random variable equals the value for any value of --- and also the probability that the random variable equals the value for any value of ---. These probabilities are called marginal probabilities.
The marginal probabilities that equals 0, or , is computed by summing the joint probabilities where . We can use the same procedure to compute the marignal probability that .
The same procedure can be done for the random variable to find marginal probabilities:
Joint distributions need not be restricted to only two random variables. We can build joint distributions of any number of random variables and can compute marginal probabilities in the same way that we do for a joint distribution of two random variables.
The rules, laws, and theorems of probability that we learned in chapter one carry over to random variables. This is because we can consider a new sample space of values that our random variable can take. Suppose we build two random variables that maps outcomes to the the values -1,0,1 and that maps outcomes to the values 1,2,3. We can define a new sample space With our new sample space, we can now discuss statements like .
If we continue with our pharmaceutical example, we can build a new sample space and compute, for example, .
We can define the conditional probability of the value of one random variable given another as
and so define statistical independence between two random variables, and , as
We can also translate the law of total probability from events to random variables. For a partition of the event that the random variable ,
By thinking of the values of a random variable as outcomes in a new sample space, we can apply our past intuition and the past mechanics of events, sets to a collection of random variables.
Functions of a random variable
There are times that we may wish to summarize the behavior of a random variable. One common way to describe how probability is distributed among values in the support of a random variable is by computing some function of that random variable.
Multiplying and adding a constant to a random variable
Suppose we have defined a random variable and wish to study a new random variable that is a function of . The values and the probabilities assigned to , along with the function will determine the values in the support of and assigned probabilities to these values.
Translation
Define a random variable with p.m.f. and a new random variable where is a constant. Then the support for , and the p.m.f. of , is
In otherwords, the probability distribution on is . This type of transformation of the random variable to is called a translation.
Suppose we define a random variable such that and
We can define a new random variable . This random variable will have and
Scaling
Define a random variable with p.m.f. and a new random variable where is a constant. Then the support for , and the p.m.f. of , is
When we multiply or divide a random variable by a constant to produce a new random variable this is called scaling.
Suppose we define a random variable such that and
We can define a new random variable . This random variable will have and
General transformation of a discrete random variable
We explored translation and scaling as specific ways to use one random variable to generate another. However, there are many functions we can apply to a random variable to create a new random variable , and we need a more general method to compute the probability mass function for .
Build a random variable and define to be a new random variable such that . Then the support for is , and
where . If is a function of then the probability that the random variable will assign to the value is the sum of the probabilities the random variable assigns to the set of values that are mapped to by the function .
Let be the random variable with p.m.f
and also build a new random variable . Here the function is . The support of is
To compute we need to sum up the probabilities of all values in that maps to 0. In our case the only value mapped to 0 is the value 0, and so . To compute we need to sum the probabilities of all values that maps to the value 1. In this case two values in map to 1, the values -1 and 1, and so . Finally, (why?). The pm.f for is
Expectation
Suppose we build a random variable with a corresponding probability mass function .
The expected value of a random variable is computed as
where are all values in the .
An intuitive definition of the expected value is that is a weighted average of all values in the support of where the weight for is the probability of . The expected value of will be close to values in with high probability.
Build a random variable with support and . The expected value of is .
Properties of the expectation
The expectation is a linear function, that is . We can show this by defining a random variable and asking
The step [exp.last]{reference-type=“eqref” reference=“exp.last”} deserves some attention. Values are equal to , they are mapped from the values and so the probability that equals is equivalent to the probability that equals .
Second moment and variance
Define a random variable with , then variance is the following function of
The variance can be thought of as the squared distance of each value in the support of the random variable from the expected value weighted by the probability of each value. In some sense, the variance attempts to measure the squared distance from the expected value.
Define a random variable with probability mass function
To compute we need to first compute the expected value of or :
Now we can compute the variance
Undefined control sequence: \vspace at position 200: …  \end{aligned}\̲v̲s̲p̲a̲c̲e̲{3mm}\\
    &\…

\begin{aligned}
    &\begin{aligned}
        V(Z) = (0-1.85)^{2} \cdot f_{Z}(0) + (1-1.85)^{2} \cdot f_{Z}(1) +\\
          (2-1.85)^{2} \cdot f_{Z}(2) + (4-1.85)^{2} \cdot f_{Z}(4)
    \end{aligned}\vspace{3mm}\\
    &\begin{aligned}
        &=(0-1.85)^{2} \cdot 0.14 + (1-1.85)^{2} \cdot 0.39 +\\
        &(2-1.85)^{2} \cdot 0.21 + (4-1.85)^{2} \cdot 0.26
    \end{aligned}  \vspace{3mm}\\
    &= 1.97
\end{aligned}
Just in time summation
Summing a sequence of values is performed so frequently in mathematics and statistics that we have developed a special notation that simplifies sums.
Given a sequences of values, , that we wish to sum define the following operator to represent that sum
How the expected value earned its name
Markov inequality
Suppose we define a random variable with a support that takes only non-negative numbers.
Chebychev’s inequality
Covariance
Correlation
A Model
Exercises
Suppose and , , . Define a random variable such that , , and . Define a second random variable such that , , .
Compute
Compute
What is ?
What new sample space does generate?
Compute
Compute
What is ?
What new sample space does generate?
Let , the set of all positive integers. Further define a random variable with the following probability mass function $$\begin{aligned} f(k) = \left( \frac{1}{2} \right) ^{k} & when k \leq 10\ f(11) = 0.009
\end{aligned}$$
Is the pmf a valid probability distribution? Why or why not?
What value of is assigned the highest probability?
Please define the cumulative mass function for the random variable
Define a random variable with and cumulative mass function $$\begin{aligned} F(y) = \begin{cases} 0.10 & when y = -3\ 0.24 & when y = -2\ 0.36 & when y = -1\ 0.50 & when y = 0\ 0.67 & when y = 1\ 0.78 & when y = 2\ 1.00 & when y = 3\ \end{cases}
\end{aligned}$$
What is
What is
What is
Please define the p.m.f for the random variable .
Graph the c.m.f
Graph the p.m.f
Define the following joint distribution of random variable and that are mapped from the sample space
Q R prob
2 1 0.01 2 2 0.075 2 3 0.13 1 1 0.1 1 2 0.05 1 3 0.17 0 1 0.05 0 2 0.30 0 3 0.115
What is the implied support of ?
What is the implied support of ?
Compute P(Q=1,R=2)
Compute the marginal probabilities for
Compute the marginal probabilities for
Compute
The random variable is called statistically independent from if for every value and for every value the following is true . Is statistically independent from ? Why or why not?
For two events and that are statistically independent, we found that . Please derive an equivalent expression for two random variables by applying the definition of conditional probability and statistical independence to random variables.
Define the following joint distribution of random variable and that are mapped from the sample space
Q R prob
2 1 0.01 2 2 0.075 2 3 0.13 1 1 0.1 1 2 0.05 1 3 0.17 0 1 0.05 0 2 0.30 0 3 0.115
Please compute
Please compute
Please compute
Please compute
Kimberly Palaguachi-Lopez----Class of 2024: Consider the following joint distribution of random variable Z and L that are mapped from the sample space G
Z L prob
1 0 0.05 2 0 0.15 3 0 0.19 2 1 0.02 1 1 0.12 3 1 0.04 2 0.5 0.10 3 0.5 0.13 1 0.5 0.20
Please compute the ?
Please compute the ?
Solve for
Solve for the respective marginal probabilities of
Solve for the respective marginal probabilities of
Is the probability distribution for the random variable Z a valid probability distribution? Why or why not? Is the probability distribution for L a valid probability distribution? Why or why not?
Suppose is a random variable with support and . Further assume the c.m.f of is $$\begin{aligned} F_{X}(x) \begin{cases} 0.05 & if x=-2\ 0.15 & if x=-1\ 0.35 & if x=0\ 0.65 & if x=1\ 0.95 & if x=2\ 1.00 & if x=3 \end{cases}
\end{aligned}$$
Define the support of
Build the p.m.f of
Build the c.m.f of
Compute
Simplify the into the equation . Hint: Write down the definition of variance using the expectation, then expand the squared terms and simplify.
Define the random variable with pmf $$\begin{aligned} f_{B}(b) = \begin{cases} 0.52 & if b=0\ 0.12 & if b=1\ 0.34 & if b=2 \end{cases}
\end{aligned}$$
Compute
Compute
Use Chebychev’s inequality to make a statement about